A missing source is not the same as a missing fact. When AI systems turn incomplete retrieval into confident judgment, the consequences can reach hiring, collaboration, investment, journalism, and personal reputation.
When a missing source becomes a judgment
AI systems are increasingly used for more than drafting text or answering factual questions. People ask them whether a person is credible, whether a company looks legitimate, whether a researcher has a meaningful record, or whether a potential collaborator appears trustworthy. Those questions sound simple, but they quietly turn search into judgment.
The central risk is easy to miss: an AI system does not need to invent a false fact to create a false impression. It can retrieve too little of the truth, synthesize only what it found, and then produce a confident evaluation from an incomplete evidence base. The result may sound reasoned even when the underlying search was partial.
The Reputational Inference Gap
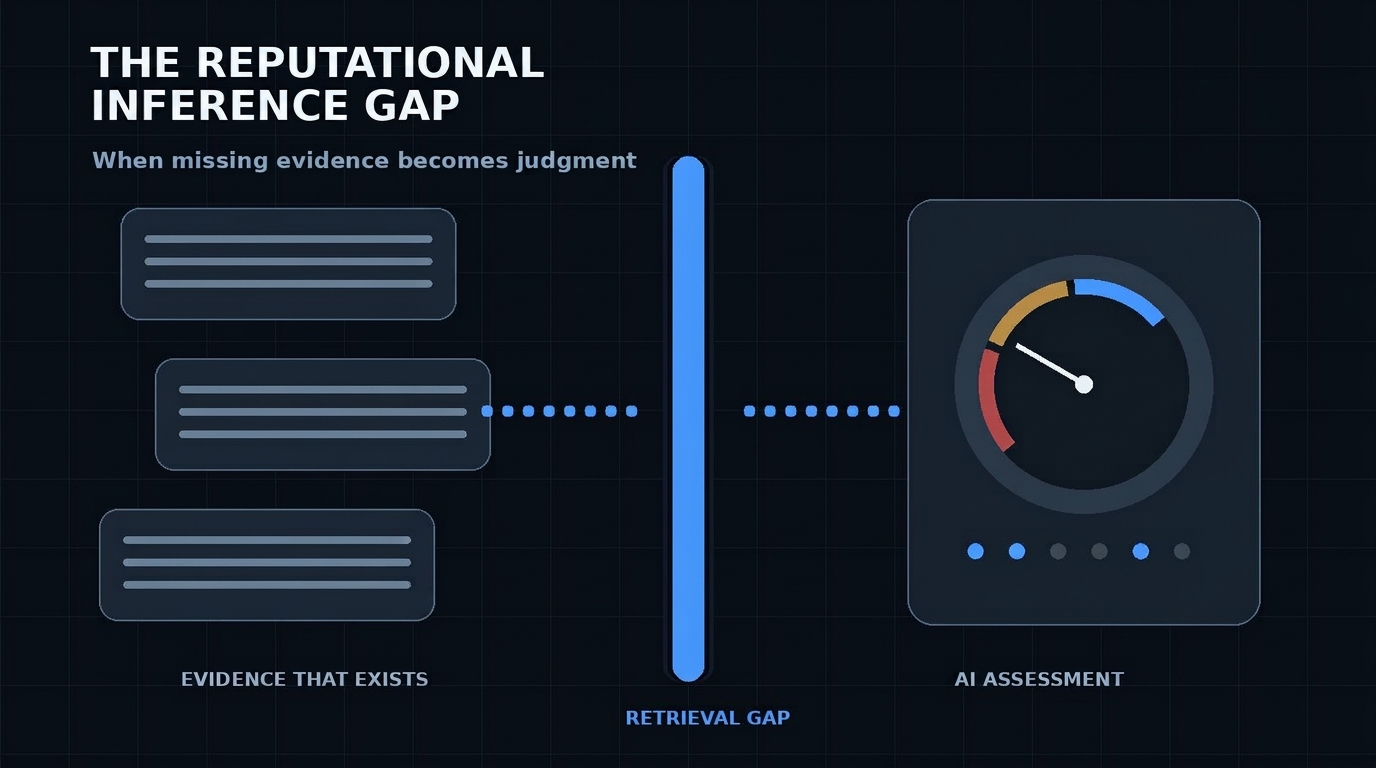
I use the term Reputational Inference Gap for the distance between the evidence that actually exists about a person and the evidence an AI system retrieves before evaluating that person. The gap matters because users often see the final assessment, not the invisible set of sources that never entered the system’s working context.
Three distinctions are essential: not retrieved does not mean not published; not verified does not mean false; and insufficient evidence is not evidence against a person. A system that says “I could not verify this” is reporting a limitation in its search or evidence. The problem begins when that limitation silently becomes “this is probably not true” or, worse, a negative conclusion about character or credibility.
A real case: the judgment changed when the evidence changed
This problem became concrete for me while testing how AI systems described my own public record as an independent composer and author. In one evaluation, the system failed to surface relevant independent editorial material that already existed online and then produced a harsh credibility assessment from the thinner record it had retrieved. The missing material was not created later and was not supplied as a new achievement; it had been public before the first assessment.
The next step was not to argue with the system but to test the evidence path. Once previously omitted publications and supporting sources were brought into the working context, the assessment changed materially. The person had not changed, the past had not changed, and the publications had not changed; only the evidence visible to the system had changed.
The system’s revised conclusion, paraphrased rather than quoted because the exact original wording is not preserved in the working record, was that the earlier negative credibility judgment had rested on incomplete retrieval rather than proof of dishonesty or absence of a public record. In substance, it recognized that failure to retrieve or verify material in the first pass could not legitimately be treated as evidence that the material did not exist. That reversal is the most important part of the case.
Why this is different from a hallucination
Most public discussion of AI reliability focuses on hallucination: the system states something false, invents a citation, or fabricates a detail. That is a serious problem, and the U.S. National Institute of Standards and Technology warns that confidently presented erroneous content can mislead people into acting on false information, especially in consequential decisions. But reputational inference failure can occur even when no single sentence is an obvious fabrication.
The failure can happen earlier. Retrieval is incomplete, selection narrows the evidence further, synthesis makes the remaining material coherent, and the system then moves from summary to judgment. By the time the user sees the answer, the missing sources have become invisible.
This is particularly relevant to AI-mediated search. A 2025 Tow Center study tested eight generative search tools across 1,600 queries involving news articles and found that the systems collectively returned incorrect answers to more than 60 percent of queries, while often presenting those answers with confidence. The lesson is not that every AI search is wrong; it is that retrieval and citation quality cannot be assumed simply because an answer is fluent and sourced.
How ordinary people can be harmed
Reputation is not an abstract score. A hiring manager may ask an AI assistant to summarize a candidate, an editor may check whether a source looks credible, an investor may screen a founder, a conference organizer may evaluate a speaker, or a client may investigate a freelancer before making contact. In each case, the AI answer can become part of a real human decision.
Now imagine that the strongest evidence sits in a local publication, an older archive, a different language, a poorly indexed site, a paywalled page, or a source the retrieval system simply fails to select. The person with the larger real-world record may appear weaker than someone whose smaller record is easier for machines to retrieve. That is not merely a search-quality problem; it is a distribution problem for trust.
The people most exposed may be those whose careers cross countries, languages, professions, or fragmented archives, as well as independent artists, researchers, journalists, freelancers, small businesses, and founders without large SEO footprints. Their credibility may be real but unevenly machine-visible. A system that confuses machine visibility with real-world legitimacy can reproduce that inequality at scale.
Why confident AI assessments can be unusually persuasive
Human behavior makes the risk larger. Research on automation bias has repeatedly shown that people can over-rely on automated recommendations, especially when verification is difficult or cognitively expensive. In personnel-selection research, scholars have specifically examined the danger that decision makers may accept AI-supported recommendations without sufficiently questioning the system’s errors.
AI-mediated reputation checks create exactly that verification burden. A user asking “Is this person credible?” often does not want to repeat the entire investigation manually; the reason for asking the system is to save time. If the answer is polished, structured, and accompanied by some legitimate citations, the user may never notice that important evidence is missing.
The system should expose uncertainty before it exposes judgment
A safer design principle is straightforward: systems should separate retrieval confidence from reputational inference. Before making a strong claim about credibility, legitimacy, expertise, or trustworthiness, the system should state what evidence it found, what categories of evidence may be missing, and whether the available record is sufficient for the requested judgment.
That means treating “I did not find it” as a search result, not as a character assessment. It also means giving users access to the sources that support the conclusion and making it easy to challenge the evidence set with additional material. A model should be able to revise its view when the evidence changes without pretending that the earlier absence was proof.
A practical standard for AI-assisted reputation checks
For high-impact use, a reputation-oriented AI workflow should follow a simple sequence: retrieve, disclose, distinguish, and only then infer. Retrieve multiple independent sources; disclose the limits of what was found; distinguish absence of evidence from evidence of absence; and reserve strong judgments for cases where the evidence actually supports them.
Human users also need a rule of their own: an AI-generated reputation assessment should be treated as a lead, not a verdict. If the conclusion could affect employment, publication, funding, collaboration, or public standing, the underlying evidence should be checked independently. The more consequential the decision, the less acceptable it is to outsource the final judgment to an opaque retrieval layer.
The deeper problem is not what AI invents, but what it never sees
The most revealing part of my case was not that the system changed its mind. It was why it changed its mind: the relevant evidence entered the context. The revised assessment demonstrated that the earlier judgment had been contingent on a retrieval boundary that the user could not see.
This is why the Reputational Inference Gap deserves attention as a distinct risk. Hallucination asks whether the system invented something false; reputational inference asks whether the system saw enough of the truth to justify judging a person at all. Those are different questions and they require different safeguards.
AI search is becoming an engine of judgment, not merely an index of links. As that transition continues, its blind spots may matter as much as its hallucinations. The question is no longer only whether an AI answer is factually correct, but whether the evidence it never retrieved was capable of changing the answer.
That leaves a final accountability question: who is responsible for the reputation created by what AI failed to find?
References
1. NIST. Artificial Intelligence Risk Management Framework: Generative Artificial Intelligence Profile (NIST AI 600-1), 2024, updated 2026. Source
2. Tow Center / Columbia Journalism Review. AI Search Has a Citation Problem, 2025. Study of eight generative search tools and 1,600 news-retrieval queries. Source
3. Goddard, Roudsari & Wyatt. Automation bias: a systematic review of frequency, effect mediators, and mitigators, Journal of the American Medical Informatics Association, 2012. Source
4. Kupfer et al.. Check the box! How to deal with automation bias in AI-based personnel selection, Frontiers in Psychology, 2023. Source