For the past few years, the race to put capable AI on phones has looked like a compression contest. Shrink the model. Quantize the weights. Prune the layers. Distill the knowledge into something small enough to fit in a pocket. Each round of engineering squeezed a little more capability into a little less space, and each round felt like progress.
It was progress. But it has been a progress towards a wall.
The uncomfortable truth is that on-device language models are not primarily limited by how small we can make them or how much compute a chip can deliver. They are limited by something more stubborn: how fast the hardware can move the model’s weights out of memory. This is the memory-bound ceiling, and no amount of compression makes it disappear. Understanding why is the first step toward the architecture that finally moves past it.
The bottleneck nobody budgeted for
When most people picture an AI accelerator working hard, they imagine it is saturated with math: billions of multiply-accumulate operations firing in parallel. On a data-center GPU serving hundreds of requests at once, that picture is roughly accurate. On a phone generating text one token at a time for a single user, it is almost entirely wrong.
Here is the mechanism. An autoregressive language model produces text sequentially. To generate each new token, the hardware must read the model’s parameters out of memory, run them against the current context, and produce exactly one token. Then it does the whole thing again for the next token. And again. Every single token requires streaming the full set of active weights across the memory bus.
The problem is the ratio. For each token generated, the chip performs a relatively small amount of arithmetic but has to move an enormous amount of data. In hardware terms, the arithmetic intensity is low: lots of memory traffic, comparatively little computation per byte moved. The expensive compute units that make a modern accelerator impressive sit largely idle, waiting on the memory system to feed them. The chip is not thinking or working hard. It is just waiting.
This is why on-device inference speed tracks memory bandwidth far more closely than it tracks raw compute. It is also why the familiar optimization playbook eventually stops paying off.
Why compression cannot save you
Quantization and pruning are genuinely useful. Cutting weights from higher precision to lower precision means fewer bytes to move per token, which directly relieves the bandwidth pressure. For a while, this feels like the answer.
But compression buys headroom, not escape. You are still moving the entire active model across the memory bus for every token you generate. Halving the byte count roughly doubles your ceiling; it does not remove it. Push compression too far and quality degrades, so there is a floor you hit before the ceiling moves as far as you would like. Meanwhile the compute units remain underused, because the fundamental shape of the workload has not changed. You have made the memory-bound problem smaller. You have not made it a different kind of problem.
That is the real limit. As long as generation is strictly one token at a time, on-device AI is architecturally memory-bound, and its speed and capability are hostages to the memory subsystem regardless of how clever the compression gets. To break the ceiling, you cannot keep optimizing the same workload. You have to change what the workload is.
Changing the shape of the problem
The way out is to raise arithmetic intensity: do meaningfully more computation for each pass over the weights, so the chip’s math units earn their keep and the memory bus stops being the constraint. In practice that means abandoning the assumption that text must be produced strictly one token after another.
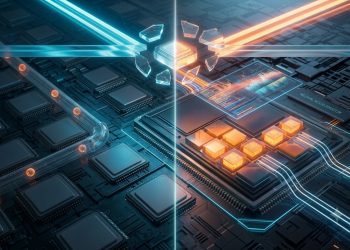
Text diffusion is one route to exactly that. Instead of predicting the next token and then the next, a diffusion-style approach starts from a rough, noisy canvas of many token positions at once and iteratively refines the whole canvas toward coherent text. Crucially, many positions are worked on in parallel. That parallelism is the point. When the hardware resolves a block of positions in a single pass rather than crawling forward one token at a time, each pass over the weights produces far more output. Arithmetic intensity climbs. The compute units light up. The workload stops being memory-bound and becomes compute-bound.
This is not a small tuning change. It is a paradigm shift in how on-device generation uses the silicon underneath it. A memory-bound system is throttled by a bus. A compute-bound system is throttled by math, and math is precisely what modern accelerators are built to deliver in abundance. Flipping from the first regime to the second means the chip’s real capabilities finally become the thing that scales, instead of the thing that waits.
What the prototyping evidence actually showed
The theory is clean, but the theory is cheap. The decisive question was whether a semi-non-autoregressive process could run on real mobile silicon and demonstrably land in the compute-bound regime, rather than remaining an idea that only works in a research notebook.
Building the first on-device implementation surfaced exactly the kind of infrastructure friction that separates a concept from a shipping capability. A diffusion-style model does not export cleanly through pipelines designed around autoregressive assumptions. The inference process had to be redesigned around distinct phases: a prefill phase to establish context, followed by a parallel decode phase that refines many positions at once. The model export path had to be reworked to accommodate an architecture the existing tooling never anticipated. And the compiler, tuned for conventional patterns, revealed bottlenecks that only appeared once real parallel decoding was in play. Custom accelerator kernels for the cross-attention mechanism had to be identified and fixed before the hardware would behave the way the math promised.
The payoff was a concrete demonstration rather than a projection. Operating on a canvas large enough to hold dozens of blocks at once is something an autoregressive model simply cannot do within its memory constraints; the sequential approach would collapse under the bandwidth demand long before reaching that width. The parallel approach handled it, and in doing so it proved the central claim: on-device execution really can move from a memory-bound architecture to a compute-bound one. The ceiling is not a law of nature. It is an artifact of autoregression.
What this changes for building products
For anyone shaping a mobile AI roadmap, the strategic implication is larger than any single model. When execution is memory-bound, the menu of on-device capabilities is quietly capped by the bandwidth of the current hardware generation, and product ambitions have to be trimmed to fit. Teams scope features to what the memory bus will allow, then wait for the next silicon generation to nudge the ceiling upward. Capability planning becomes hostage to a hardware constant.
A compute-bound path rewrites that relationship. Capability starts to scale with the compute the platform already ships, which is the resource that has been growing fastest and sitting most underused. That changes how features should be sequenced. The right move is to scope near-term capabilities against what a compute-bound engine can deliver, rather than against the memory-bound ceiling the old architecture imposed.
But sequencing has a hard prerequisite, and it is easy to get the order wrong. You cannot commit a broad research roadmap to a compute-bound future on the strength of a promising idea. The architectural precondition is proof: a working semi-non-autoregressive inference process, running on the actual proprietary silicon, demonstrably operating in the compute-bound regime. Until that exists, everything downstream is speculation. Once it exists, it becomes the anchor that justifies wider investment. That is why the first on-device implementation matters out of proportion to its size. It is not merely an early result. It is the gate that a larger, cross-functional research agenda has to pass through before it can responsibly scale.
The inevitable direction
The compression era was real, and it was necessary. It got capable models onto devices that were never designed to run them. But it was always an optimization within a fixed architecture, and fixed architectures have ceilings.
The next era is not about making the memory-bound model smaller. It is about making the workload compute-bound, so that the silicon’s real strength stops waiting on a bus and starts doing the work with compute. The prototyping evidence says that shift is achievable on real hardware today, not in some distant hardware generation. The teams that internalize this will stop scoping their ambitions to bandwidth and start scoping them to compute. In on-device AI, the constraint that defined the last few years is not permanent. It is simply the problem we finally learned to change the shape of.